Math-to-Silicon Synthesis
Rapidly transforming complex algorithms into production-ready hardware logic.
ACE builds ultra‑efficient FPGA math engines and Deterministic Edge AI cores—custom or off‑the‑shelf—delivered in days, not months.
ACE is committed to providing the fastest path from mathematical theory to hardware reality. Through our focus on Engineering Velocity, we deliver automated 'Math-to-Silicon' synthesis that ensures absolute determinism and bit-perfect predictability for the most demanding real-time applications.
Rapidly transforming complex algorithms into production-ready hardware logic.
Guaranteeing bit-perfect, predictable performance for real-time control loops.
Specialized hardware acceleration for both high-stakes Defense and Industrial sectors.
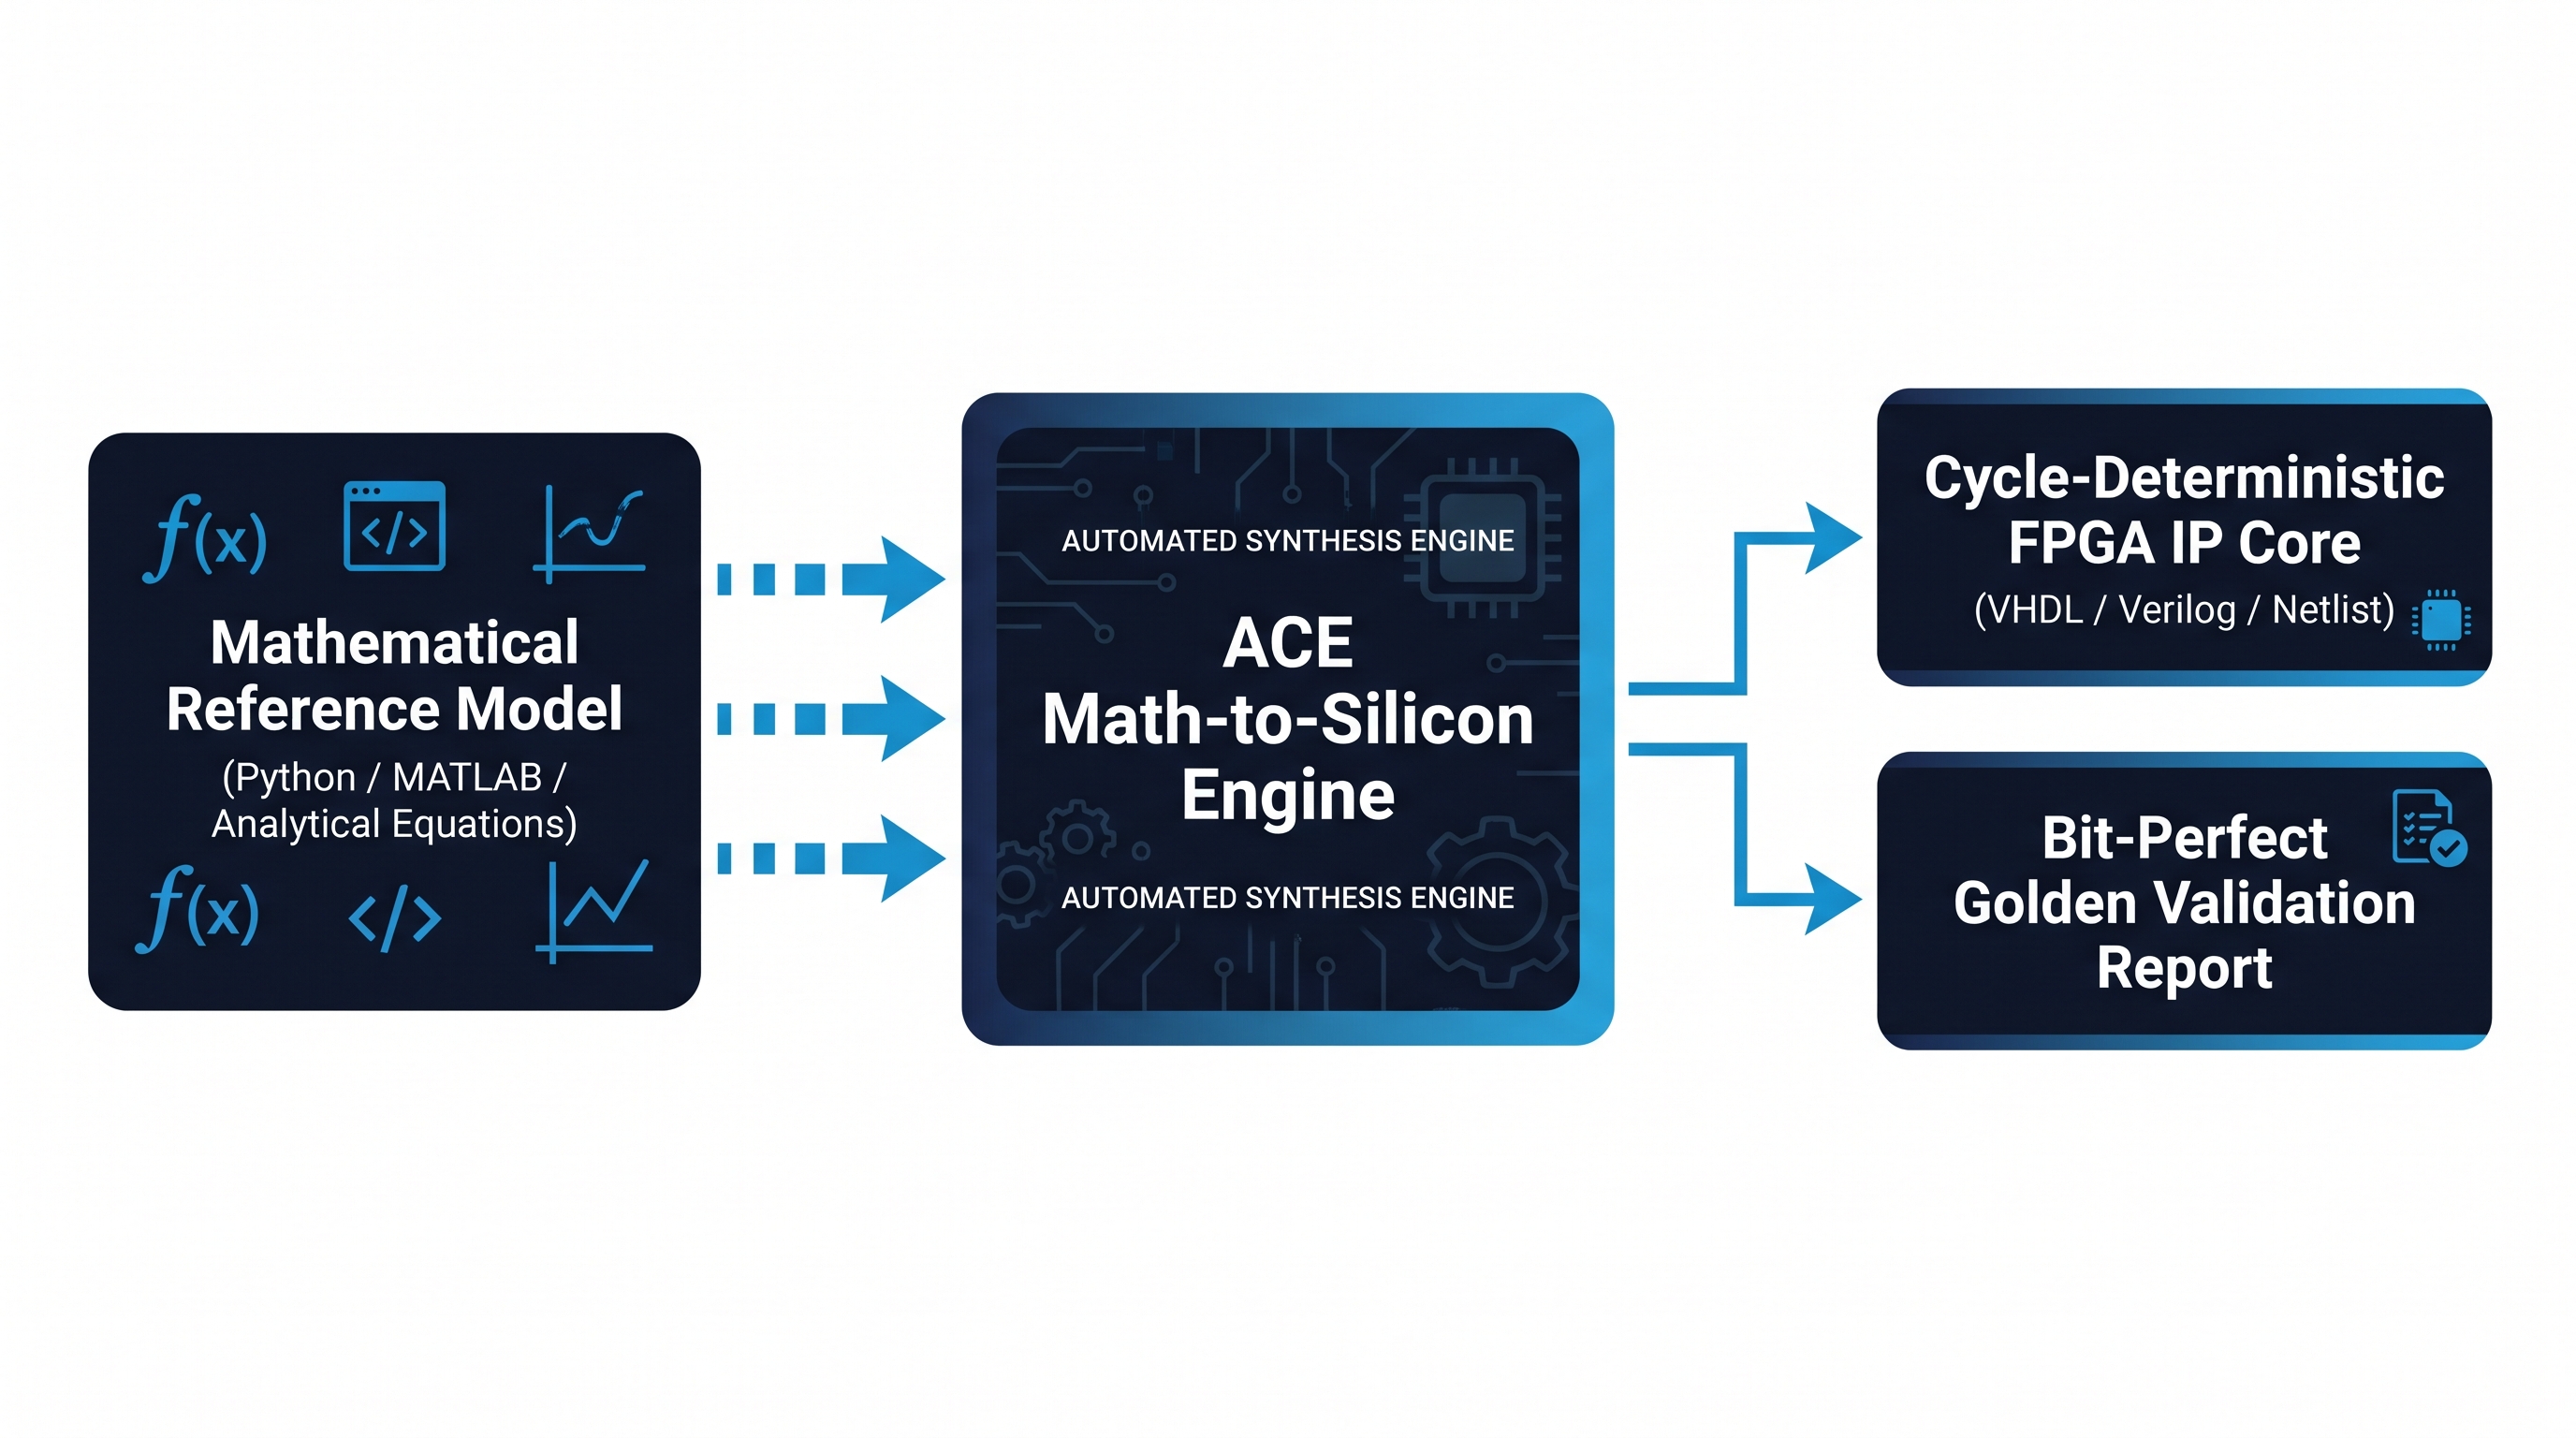
Explore our existing portfolio as a starting point. Beyond these standard cores, customization is our core strength. We use automated workflows to rapidly transform your unique requirements into production-ready RTL, ensuring the final hardware fits your system perfectly. We deliver area optimization that standard High-Level Synthesis (HLS) simply cannot match. By pushing the boundaries of RTL efficiency, we enable you to migrate complex functions—traditionally locked in software—directly into high-performance hardware logic.
| Core ID | IP Core Name | Documentation |
|---|---|---|
| ACE90011 | Multi-Sensor Extended Kalman Filter | View Datasheet → |
| ACE701189 | Forward Kinematic 6-DOF Solver & Velocity Jacobian | View Datasheet → |
| ACE980789 | Closed-Loop 6-DOF Inverse Kinematics Accelerator | View Datasheet → |
| ACE901003 | Damped Pseudo-Inverse Solver 3×6 | View Datasheet → |
| ACE910N01 | Neural ACE Motion Control & Dynamic Friction Compensation Accelerator | View Datasheet → |
| ACE600003 | Fractional Delay Coefficient Generator (21-Tap Sinc) | View Datasheet → |
| ACE808066 | Cholesky 6×6 Linear Solver | View Datasheet → |
| ACE801044 | QR Givens 4×4 Matrix Inverter | View Datasheet → |
| ACE800333 | Concatenated 3×3 Matrix Multiplier (AMD UltraScale+) | View Datasheet → |
| ACE80A333 | Chained Triple Matrix Multiplier (Intel Cyclone V) | View Datasheet → |
Bridge PyTorch neural networks directly into cycle-accurate, zero-jitter FPGA silicon.
Designed for mission-critical physical dynamics, robotics, and real-time control loops where standard processors introduce latency and jitter.
Neural ACE delivers fixed-cycle INT8 execution, runtime reconfigurability without bitstream reloads, and a constant hardware footprint regardless of model depth.
Data Privacy note: By contacting us via email, you agree that we will use your provided contact details and mathematical specifications solely to evaluate project feasibility during our early-access phase. We do not sell or share your personal information with third parties. We may use standard web analytics tools to monitor basic, aggregated website traffic to improve our site performance.